An Adversarial Multi-Agent Pursuit Game for Locomotor Agility Pretraining
November 2026
CoRL 2026 · RoboLetics 3.0 WorkshopRunner-up, Best Paper
Nathan A. C. Hogg, Matt Hyatt, Neil Klingensmith, George K. Thiruvathukal
Humanoid robots learn to lunge, dodge, and dive by playing competitive tag against each other through league-based self-play.
Reinforcement LearningSelf-PlayPPOMuJoCo WarpmjlabHumanoid LocomotionUnitree G1
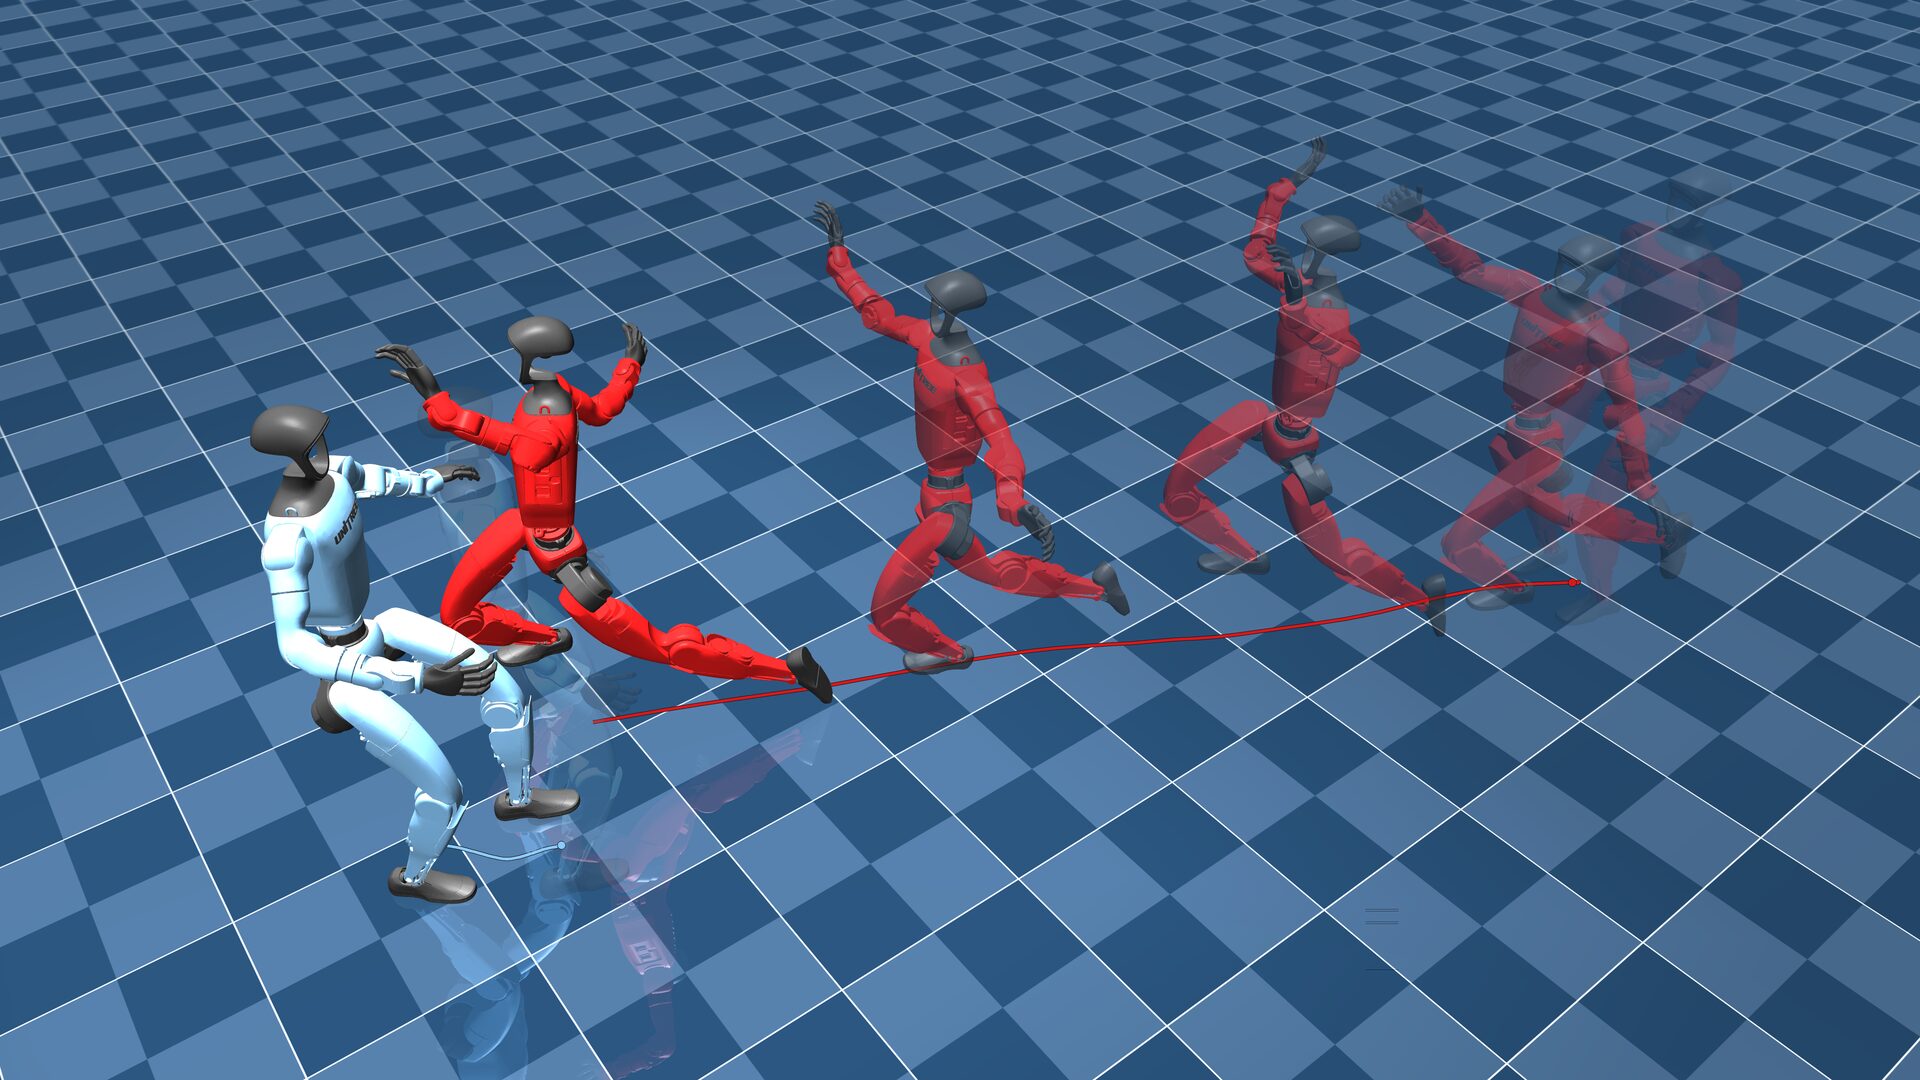
Most humanoid locomotion controllers are trained either with carafully shaped dense rewards or by tracking reference motions. Both plateau: once the reward is maximizedm, the controller stops learning new behavior. We asked whether competitive self-play, the recipe behind superhuman play in Go, StarCrafy, and hide-and-seek, could keep a locomotion controller improving from nothing more than a sparse game outcome.
Highlights
- Accepted to the RoboLetics 3.0 workshop at CoRL 2026 and named Best Paper runner-up.
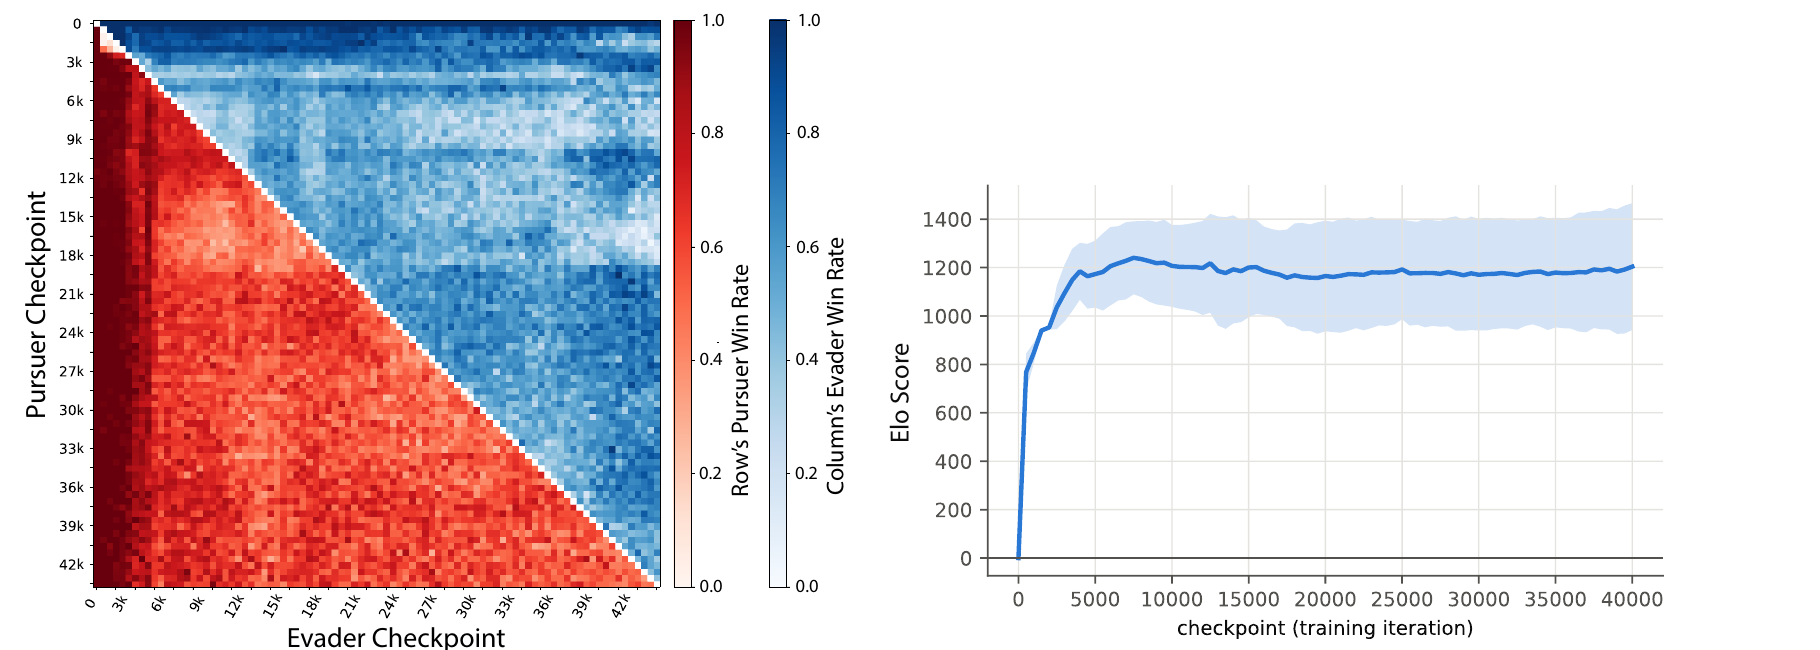
- Built a multi-agent competitive league environment for humanoids with PFSP opponent sampling.
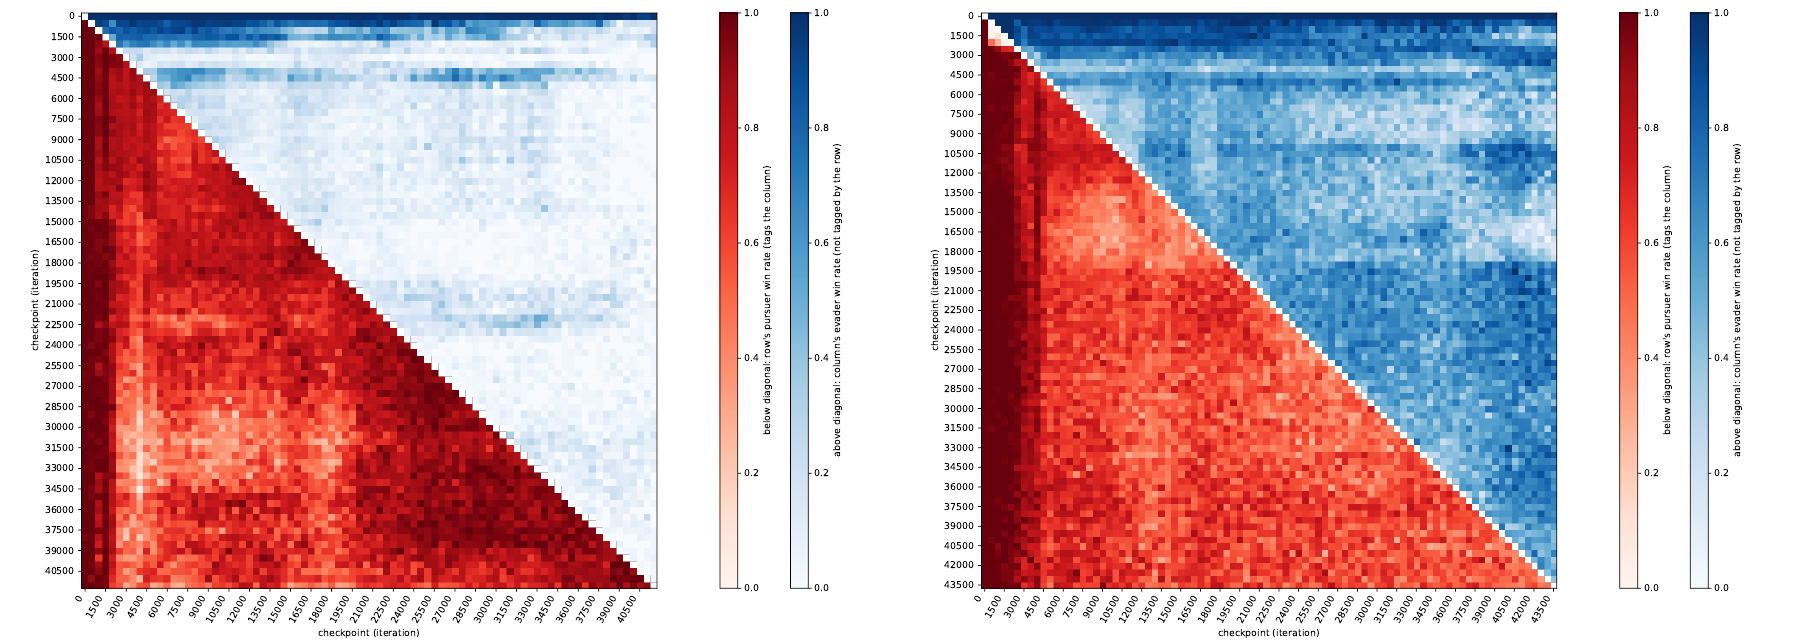
- Designed an adaptive role-sampling strategy that fixes pursuer/evader difficulty imbalance and stabilizes training.
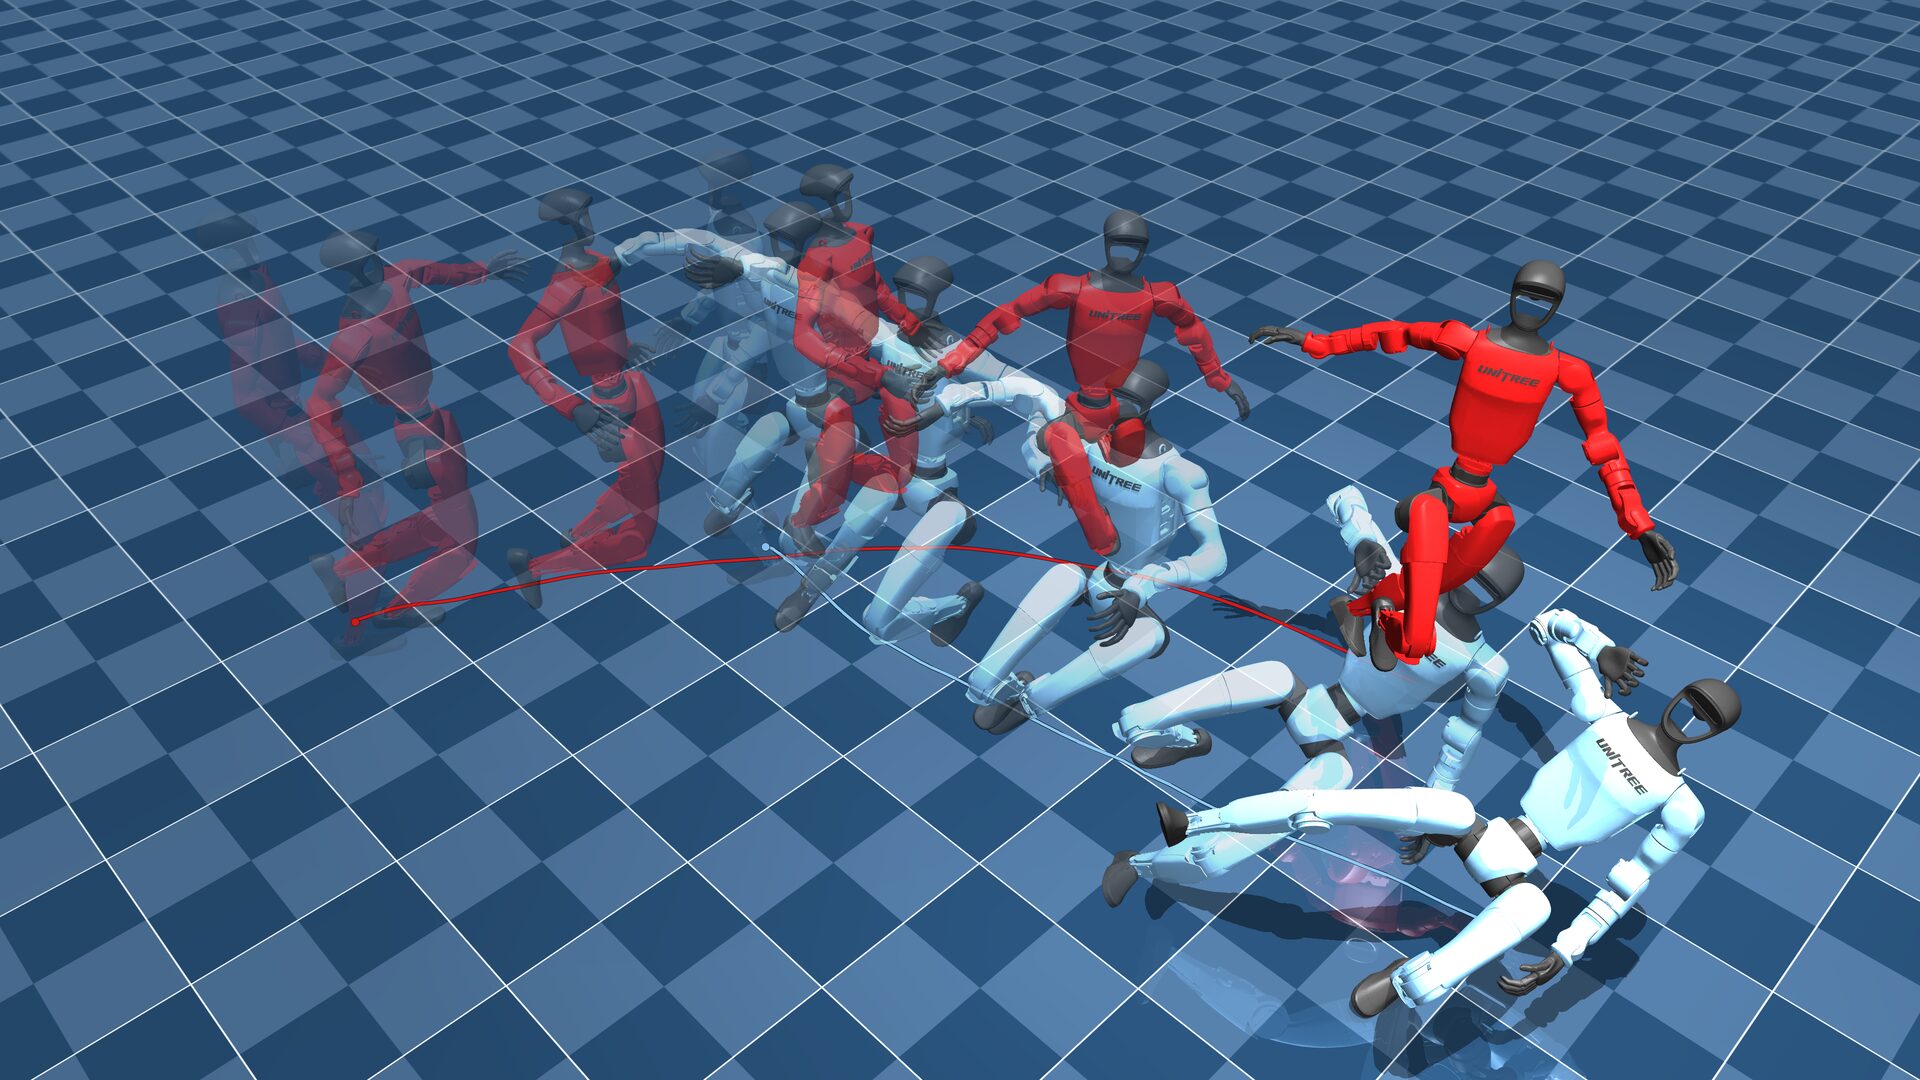
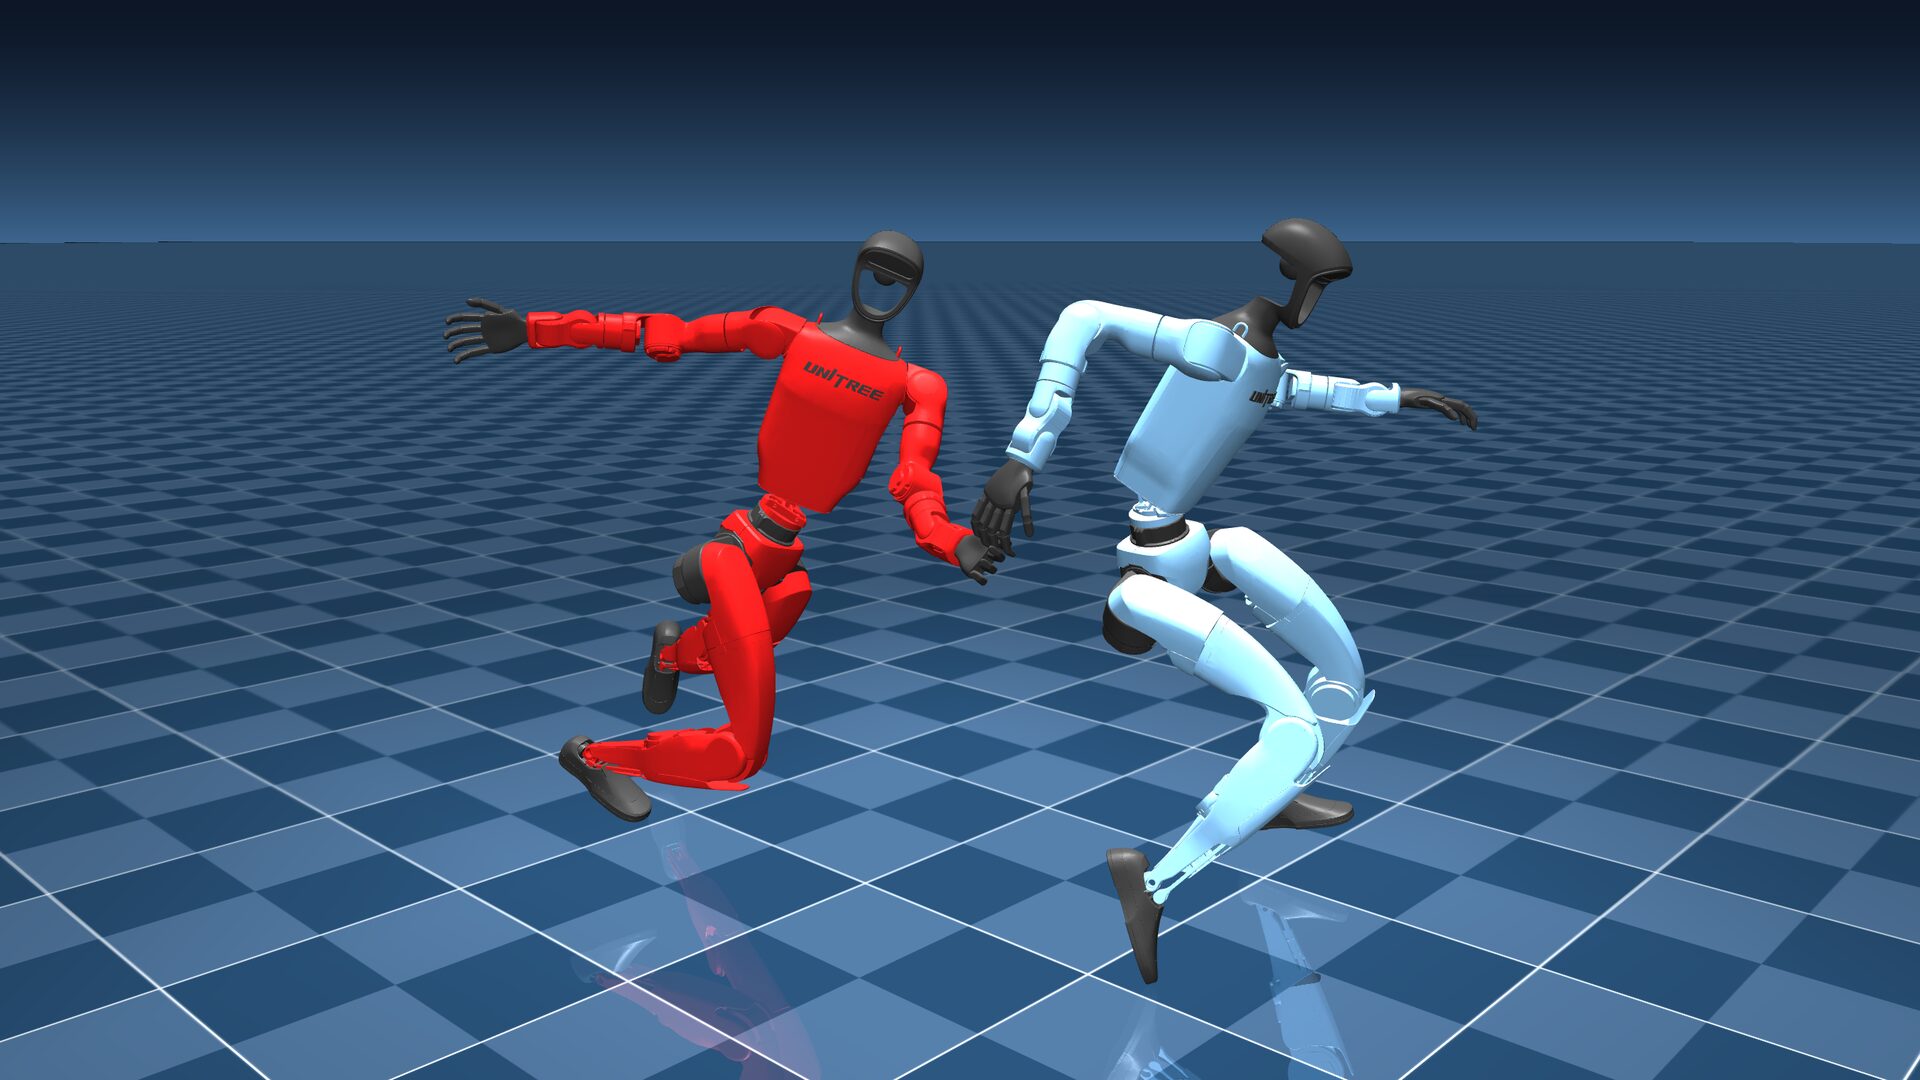
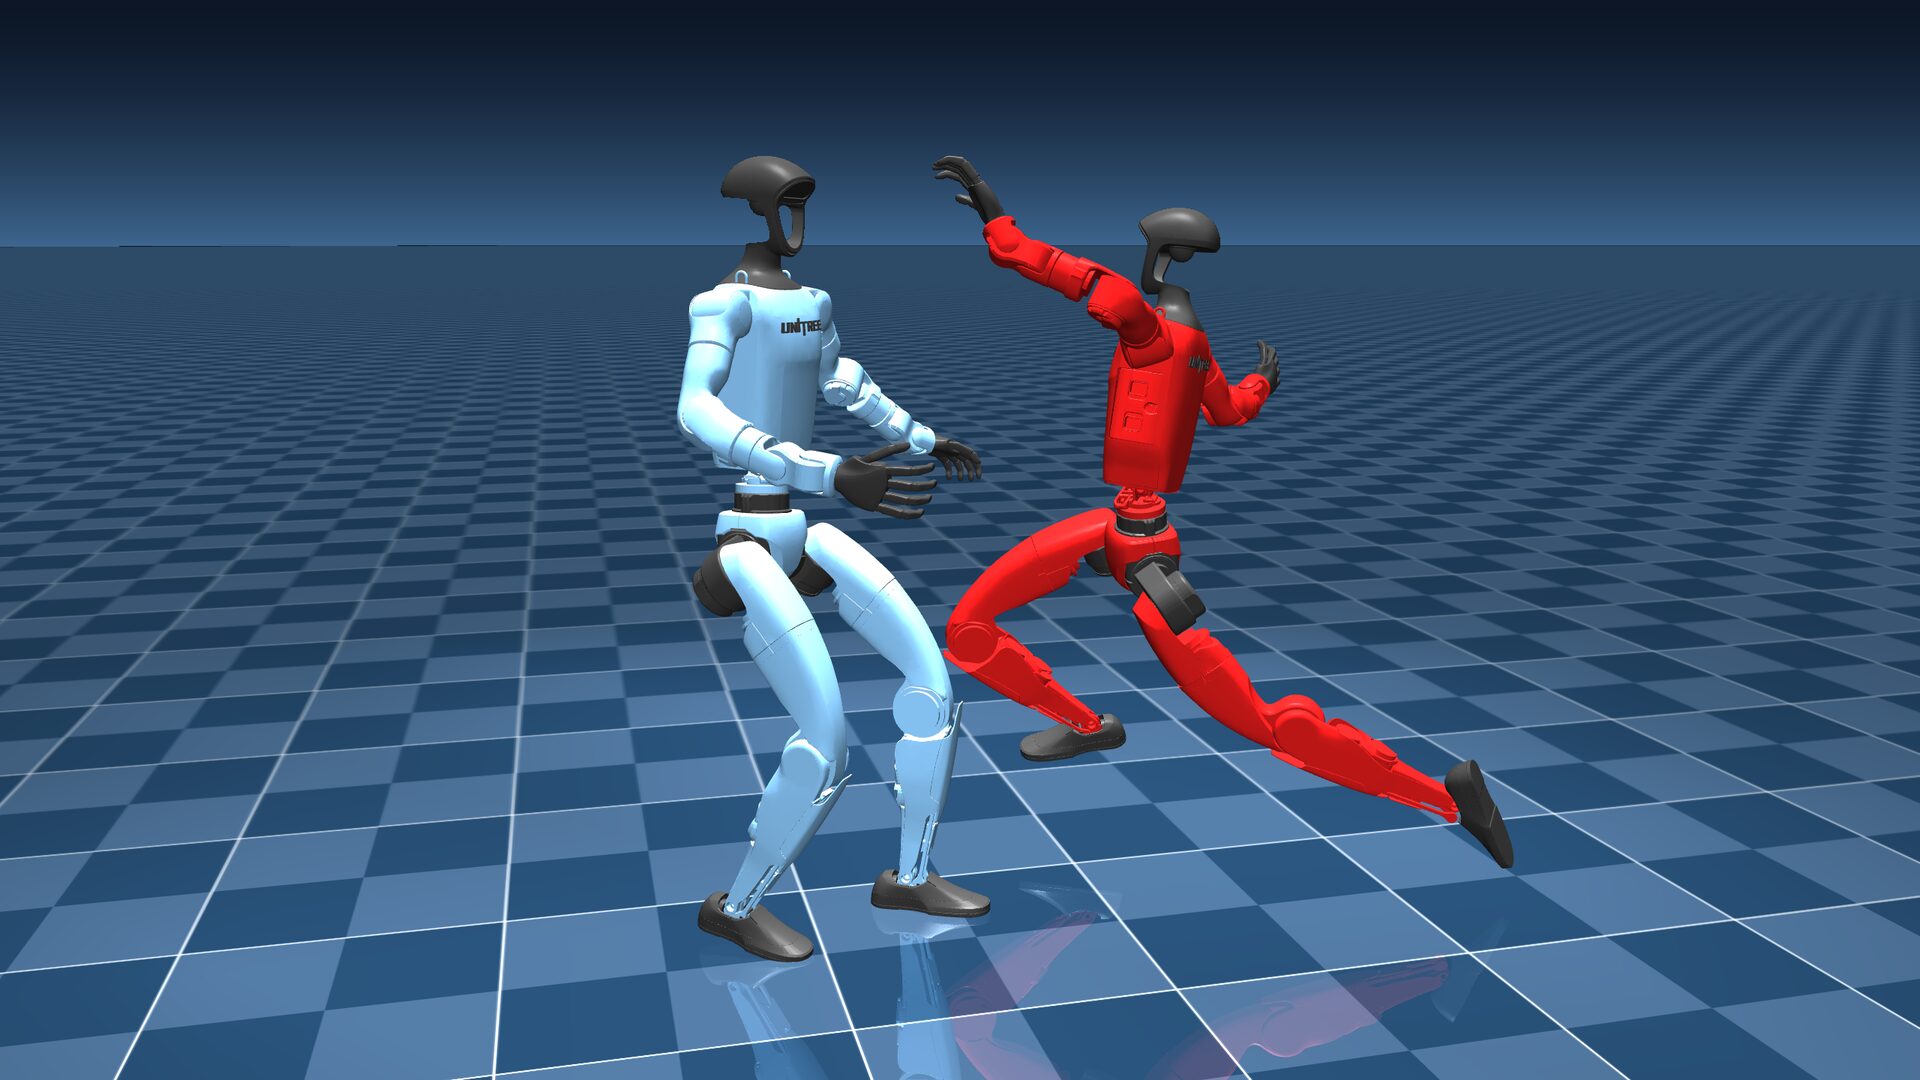
- Emergent lunging, dodging, diving, and sprinting from a sparse win/loss reward — no reference motions.
Gallery